Platform · Data Movement
Move Data Without Pipeline Code.
Configure a load once, without pipeline code, and the agent runs it. Full loads ship today. Incremental loads, which read only the records that changed, are on the roadmap, and so is change data capture (CDC).
How It Works
From Agent Deployment to Data in Motion.
Deploy an agent and connect your source. Amfelt handles the rest, from extraction to landing in your target platform.
Apache Arrow Between Connectors.
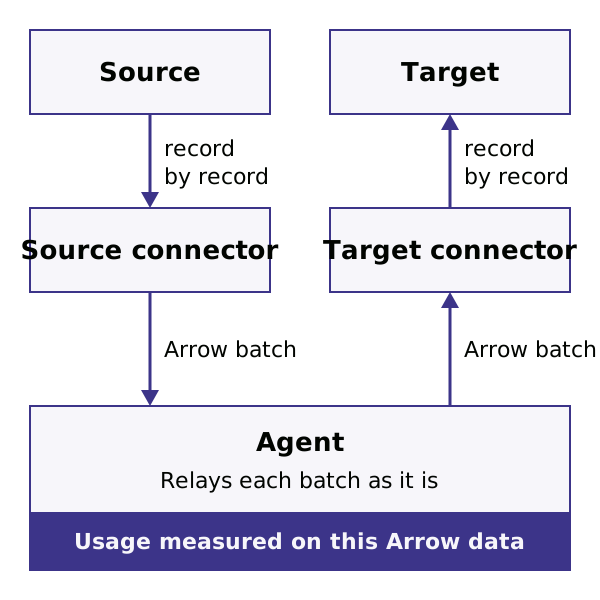
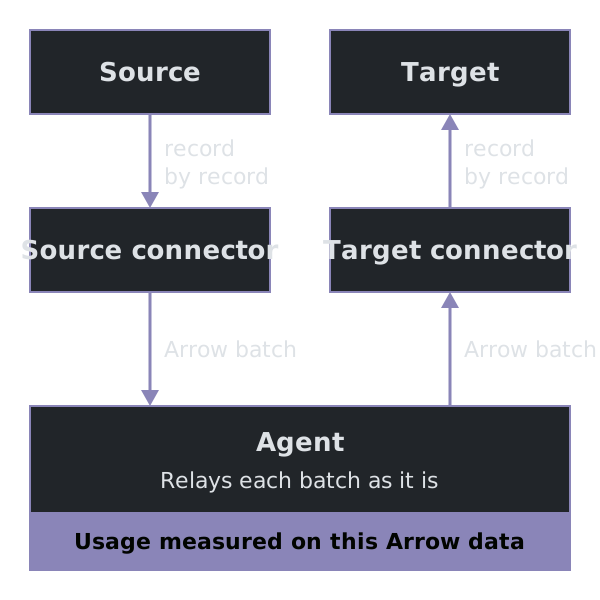
Source connectors pack records into Apache Arrow record batches, and the agent relays each batch to the target connector as it is. Reading from the source and writing to the target still happen record by record. Carrying the columnar format all the way into source and target is the next step on our roadmap. Your usage is measured on the Arrow data the agent relays.
Quality Checks on Every Sync.
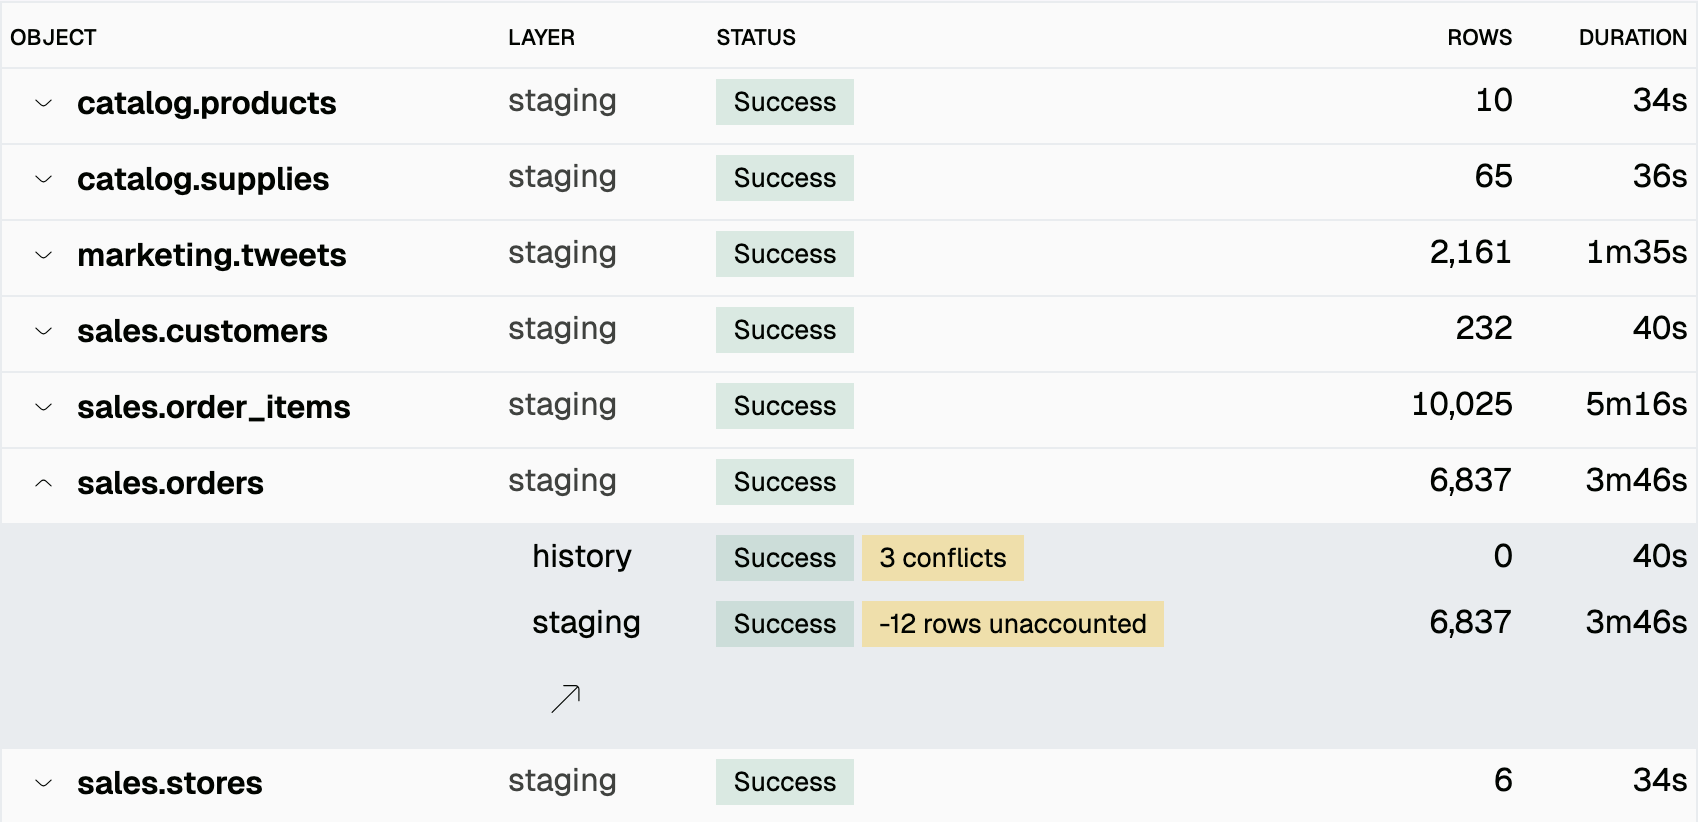
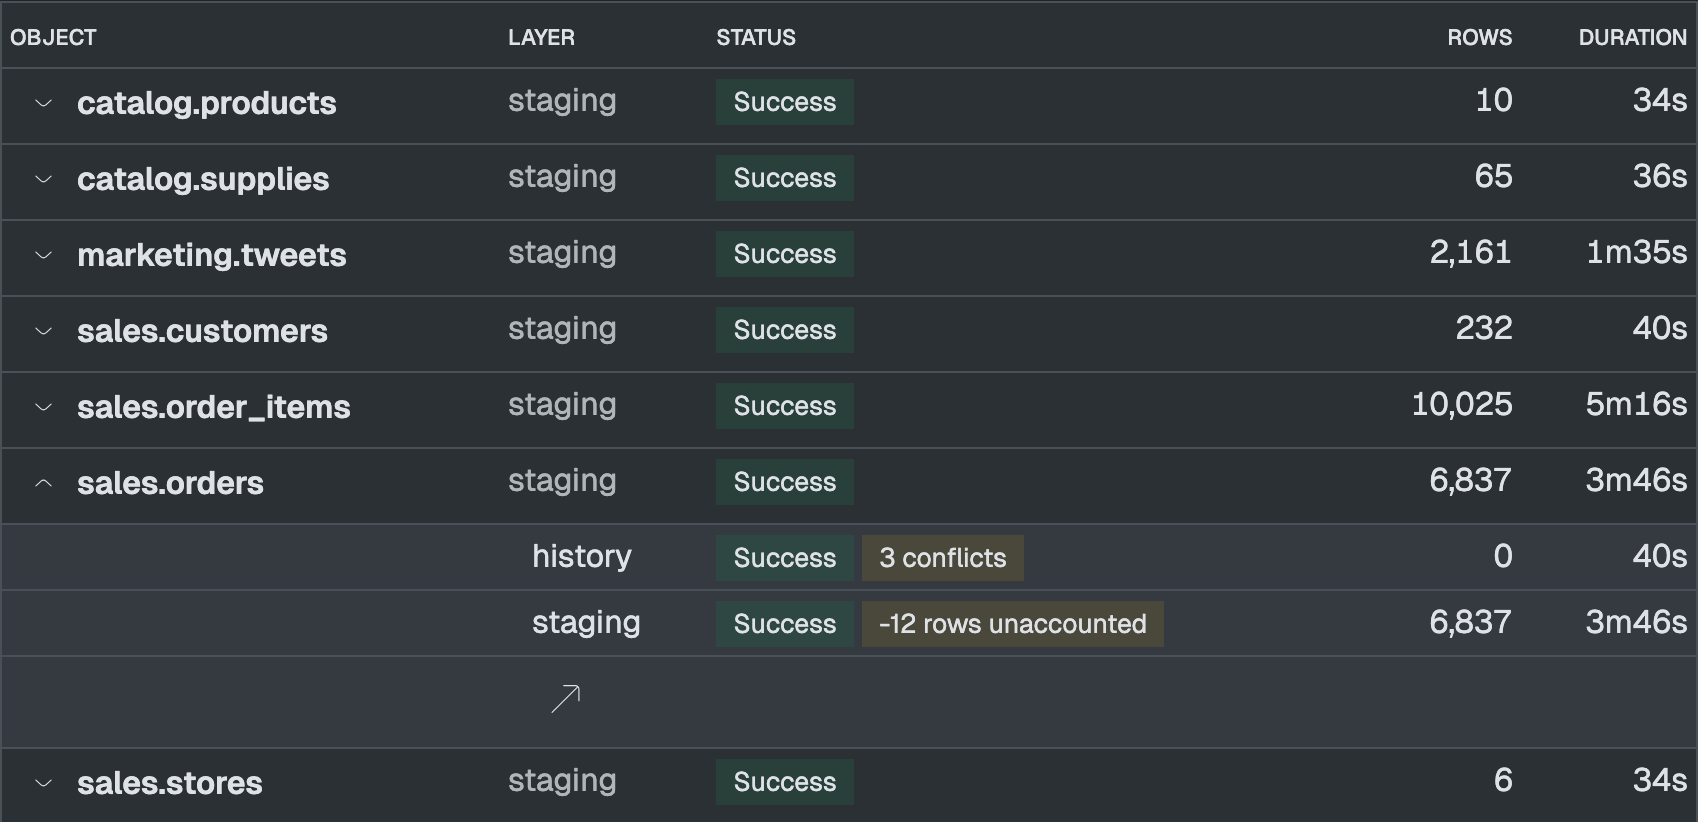
Every sync checks what it landed. After each table loads, Amfelt compares the landed record count with what it extracted and raises a warning when they differ. Where you configure an event-time threshold the run also warns about late-arriving records, and tables in append mode report records that changed under a key the history already holds.
Load Strategies, Today and Next.
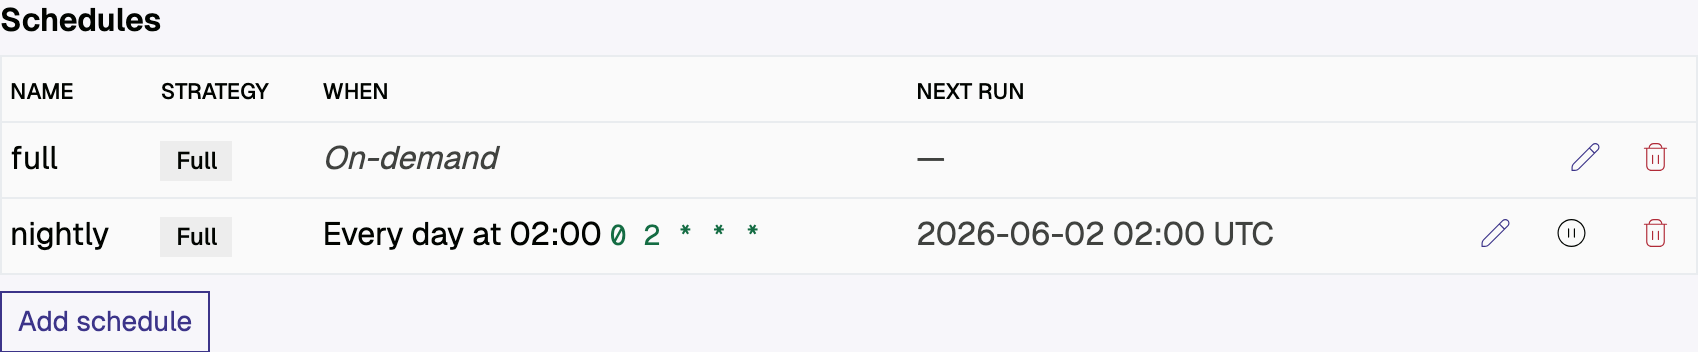
Full loads ship today and suit snapshots and small tables. Incremental loads, which read only the records that changed since the last run from a cursor such as a modification timestamp, are on the roadmap, and so is CDC for near-real-time freshness. You set the strategy per run, and Amfelt generates the load logic.
Put Your Data in Motion.
Join the waitlist, or
Ask Us for a Demo
to see data movement in action.